Showing posts with label DICOM. Show all posts

Saturday, 8 January 2011

Almost useful

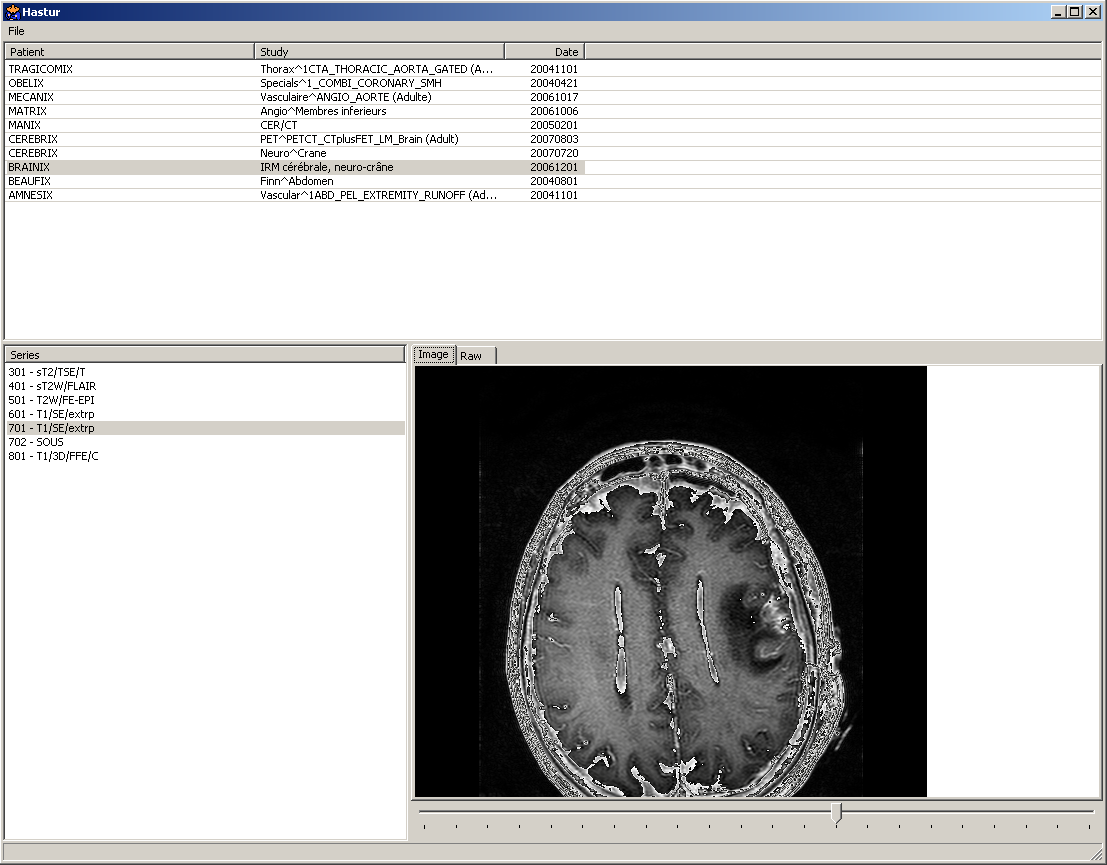
A milestone has been reached! A (single frame, non-JPEG) image now displays in the UI. OK, so it only really works for images whose dynamic range doesn't overflow the pixel intensity and cause sharp white-black transitions and there's no interpolation of the image to fit the display or scaling of pixel intensities to fit the width and centre but it's on the screen damnit :P

Intensity scaling and multiframe I can see how to do. Interpolation is simple in theory but the bugbear is going to be JPEG. I'm pushing that squarely onto the back burner for now as the only data I've seen with JPEG encoding is the Osirix example stuff. For now I'm pleased that I can build Hastur/DicomH on my work computer and actually have something that's useful. Admittedly it's more useful for looking at the raw data than the images right now but I've not seen any other program that allows me to look at the raw so easily, free or otherwise.

Proof is what we like so it's time to pony up the screenie... You can see the white-black wrapping issue clearly in the CSF and the skin.

Big steps forward since last time:
  • Study (patient) list now reacts to item selection by populating the series list
  • Series list reacts to item selection by putting the images for the series into the right hand panel
  • The slider below the right hand panel allows the user to move through the images in the series

Two immediate problems I need to fix. The current SOP instance is rendered to text on the "Raw" tab no matter if the tab is visible or not. Since this is primarily concatenating immutable strings to produce new immutable strings, this is rather expensive in terms of repeated memory allocation and garbage collection. This is fixable as soon as I can figure out which events to intercept on which windows. The second one is rather nastier. Trying to render certain images causes the stack to grow beyond 8MB. I suspect a space leak from incorrect processing of the pixel list. Fixing this may involve a fold, in my imperative mind one of the darker and more mysterious parts of Haskell along with monads.

There's so much yet to do. How quickly it gets done depends on how good I am at resisting the draw of Lord of the Rings Online :P

Thursday, 28 October 2010

Appearances Deceptive

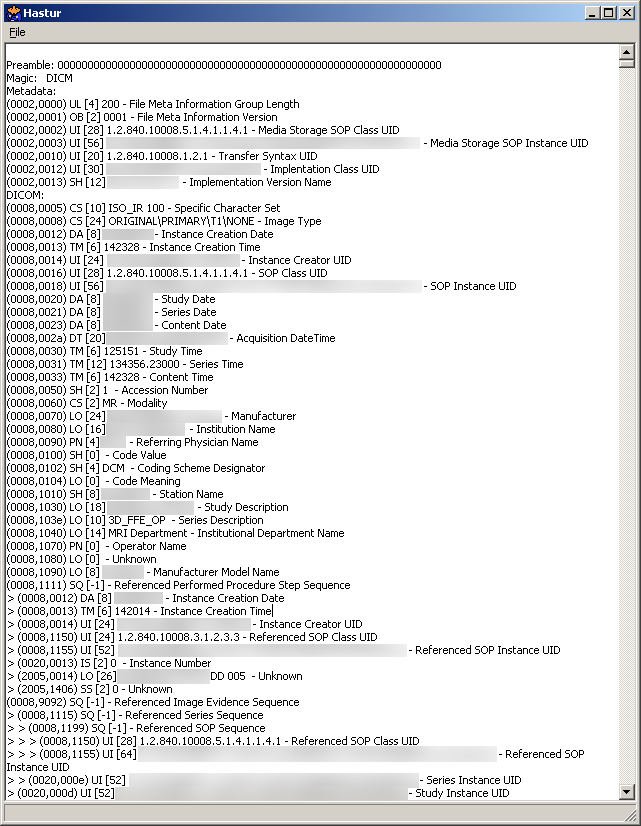
Another post, another screen shot. Almost looks like a real app :P

Differences are actually quite large though and quite a bit under the UI. An Sqlite3 database holds minimal patient, study and series info. Directories can be parsed for all their contents, recursively descending into sub-directories if desired. It's passably fast at parsing files and importing into the database too, at a bit over 1GB/min. That seems to be IO limited though as the CPU usage on my quad core peaks at about 10% much of which is system time. That will slow down as more data is inserted per file into the database so we'll have to see how bad it gets. Quietly pleased that it went through a lot of data without barfing once :)

The patient list does nothing but scroll and look pretty so far. The decoded file in the bottom right panel is one that was read independently of the database and patient list. There's no way to navigate to a file from the patient. Yet. Not least because individual files/images are not stored in the database yet...

I downloaded a whole bunch of the example files for Osirix only to discover they're mostly using the JPEG2000 transfer syntax. Arg. Vaguely fortunately, only the pixel data uses the actual JPEG2000 compression and the rest of the data is explicit VR little endian. Considerable staring at the standard and a hex editor, the addition of a new element decoding function (about 10 lines) and Hastur now reads all the metadata.

The pixel data itself is going to be a lot more trouble. It's actually held as an encapsulated document in the pixel data tag. The encapsulated document is a series of fragments encoded in a similar way to an SQ element. You can see the hex that delineates the individual fragments in the screen shot, the delimiter is "feff00e0". It won't be hard to write a parser to chew through the encapsulated document but since I don't have a JPEG2000 codec, that will wait.

Next up is storing files and images, linking bits of the UI together and figuring out the widget layout black art.

Friday, 8 October 2010

Tough Test Postponed...

...since it's far more important to have a custom icon on the main window of your UI :)

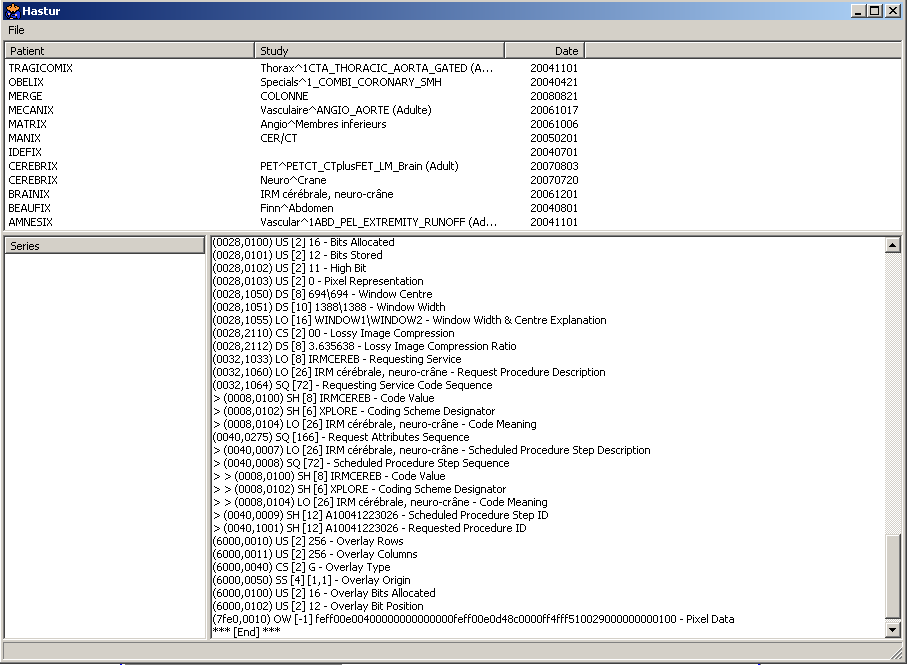
Much reading, an install of wxWidgets and wxHaskell, much more reading and many coffee later and Ihave something that might yet grow into something useful.

Since I both suck at naming and am quite fond of Cthulhu mythos, Hastur now exists. Terribly amusing pun on Hastur as he's the "One That Must Not Be Named". Hohoho. :P

Screenie here showing the first part of the aforementioned 40MB DICOM file.

BlackMage icon from Final Fantasy.

Monday, 20 September 2010

Shambling Onward

The DICOM library has ballooned somewhat since last time :/ On the upside, the basic parser can now handle both of the simplest little-endian encoding schemes, all the 30+ possible value representations (VR - tag content type) and even nested sequences (both explicit and undefined lengths). I need to think about the exposed API and how to make it usable and also about how to get rid of the inelegant staircases of if-then-else in some methods. Ugly but it does actually work. This both surprised and pleased me the first time it ploughed, without error, through a 40MB multiframe file chock full of nested sequences and dumped it in readable form onto the console.

The library is now split out into modules with defined purposes (bytestream parsing, data dictionary, pretty printing and file reading) and only a very small amount of code has to live in IO. The rest of it is pure, albeit in fairly imperative form.

The implicit little-endian encoding is going to cause me a great deal more typing. Unlike the explicit LE encoding which supplies the VR in the tag itself, the implicit encoding expects you to just know what VR corresponds to each numerical tag. The only solution I know to that is to build a dictionary with the numerical tag as the key. This works as expected with the side-benefit that I can store the tag's textual description along with the VR for use when pretty printing. I do wonder how time consuming this will be to construct every time the library's used. There are a huge number of tags defined in DICOM of which I've used 300 and they took long enough to enter. Perhaps that is the price for trying to decode such a huge standard :/

A tough test to come is whether all this data can be successfully re-encoded into a bytestream then a file and read by an existing DICOM library. That will have to wait though, I need to see what I can do with the in-memory representation and that means it's time to build a UI app to look at pretty pictures in. wxHaskell here we come...

Thursday, 2 September 2010

Baby steps in Haskell

After lots of reading and sometimes comprehending over an embarrassingly long time, I now have a very limited but actually working piece of code in a functional language.

Usually, when trying to learn a new language, the hardest thing is deciding on a vaguely pointful thing to build as the learning experience. Not this time. I wanted to create a library for dealing with DICOM medical imaging data. The format's complex enough (lots of optional stuff, various encoding schemes, heirarchical object layout, etc) to be interesting and there are few really good parsers out there for it in procedural languages I'm used to.

There probably still won't be a good one for Haskell when I've finished but I'm hoping to have learned a lot. It's certainly been very hard going getting even this far but the following is a fragment of the output from my first efforts:


Prelude: 0000000000000000000000000 ... 000
Magic: DICM
Metadata:
[ (0002,0000) UL [4] "\192\NUL\NUL\NUL"
, (0002,0001) OB [2] "\NUL\SOH"
, (0002,0002) UI [26] "1.2.840.10008.5.1.4.1.1.4\NUL"
, (0002,0003) UI [56] "1.3.12.2.1107.5.99.2.1951.30000009050612303648400002557\NUL"
, (0002,0010) UI [20] "1.2.840.10008.1.2.1\NUL"
, (0002,0012) UI [20] "1.3.12.2.1107.5.99.2"
, (0002,0013) SH [16] "XXXXXXX"
]
DICOM:
[ (0008,0005) CS [10] "ISO_IR 100"
, (0008,0008) CS [22] "ORIGINAL\\PRIMARY\\M\\ND "
, (0008,0012) DA [8] "2009XXXX"
, (0008,0013) TM [14] "140340.156000 "
, (0008,0016) UI [26] "1.2.840.10008.5.1.4.1.1.4\NUL"
.
.
.
]


Doesn't look like much but it's decoded the group and element info (0002,0001) etc, the value representation (UI, CS, OB, etc) and correctly parsed the right number of bytes for the value. It's also split the file into the encapsulation (prelude, magic and metadata) and the actual DICOM object.

Ok, there's no error handling, it only knows one encoding scheme, doesn't grok heirarchical objects and there's no error handling but it's only 140 lines of code. A good third of that formats it nicely for printing on the console though so under 100 lines for a parser just blows me away. For what it does, that's probably excessively verbose but first it needs to work, then it can be refined and finally, if necessary, it can be made faster.

I don't think I've ever been so pleased with so little code before :o Haskell is very expressive but OMG has it been hard work learning to write even this little bit :/